How AI Is Reshaping Commercial Real Estate Investment Analysis and Deal Evaluation

Commercial real estate has long been one of the most data-intensive industries in the world, yet for decades it relied on manual spreadsheets, fragmented databases, and the subjective judgment of individual analysts. That era is ending. Artificial intelligence is now penetrating every layer of the CRE investment lifecycle — from initial deal screening to long-term asset management — and the firms that adapt earliest are gaining a measurable competitive edge. Understanding how this transformation is unfolding, and which tools are driving it, is essential for any investor, broker, or asset manager operating in today’s market.
The Data Problem That Has Always Plagued CRE

Unlike equities or fixed income, commercial real estate lacks a centralized exchange. Pricing is opaque, transaction data is often delayed or incomplete, and comparable analysis requires significant manual effort. A single underwriting package for a mid-market office or industrial asset can involve dozens of variables — rent rolls, lease abstracts, operating expense histories, market vacancy trends, cap rate benchmarks, and debt service assumptions — all of which must be synthesized quickly if a deal is to be evaluated competitively.

This fragmentation has historically created two problems. First, smaller investment shops without large analyst teams are structurally disadvantaged against institutional players who can throw more human capital at due diligence. Second, even well-resourced firms are vulnerable to errors and blind spots when analysts are overwhelmed by deal volume. AI addresses both problems simultaneously by automating data aggregation, standardizing financial modeling inputs, and surfacing risk signals that human reviewers might miss under time pressure.

Underwriting at Machine Speed

One of the most immediate applications of AI in commercial real estate is accelerating the underwriting process. Traditional underwriting timelines — often measured in days or weeks — are being compressed to hours. Machine learning models trained on historical transaction data can generate preliminary valuations, stress-test rent assumptions against market scenarios, and flag properties where the seller’s pro forma appears optimistic relative to actual submarket performance.

This speed advantage is not merely operational. In competitive deal environments, the ability to deliver a credible, data-backed offer faster than a rival bidder can be the difference between closing and losing a transaction. AI-powered underwriting tools also reduce the cognitive load on senior analysts, allowing them to focus on qualitative judgment — tenant credit quality, local market relationships, repositioning potential — rather than spending hours building and checking financial models from scratch.

Scenario Modeling and Sensitivity Analysis

Beyond base-case underwriting, AI enables more sophisticated scenario modeling than most teams could realistically produce manually. Dynamic sensitivity analyses — showing how IRR and equity multiple shift across dozens of combinations of rent growth, exit cap rate, and financing assumptions — can be generated instantly and updated in real time as market conditions change. This gives investment committees a far richer picture of downside risk and return distribution than a single-point estimate ever could.

AI-Driven Demand Signals in Commercial Real Estate

The influence of AI extends beyond internal investment processes. It is also reshaping the physical demand landscape for commercial real estate itself. Data centers, AI research campuses, and advanced manufacturing facilities are among the fastest-growing property types in the current cycle, driven directly by the infrastructure requirements of the AI industry. According to JLL’s analysis of how AI is creating new demand in commercial real estate, the buildout of AI infrastructure is generating significant absorption across industrial, data center, and specialized office segments — a trend that sophisticated investors are actively positioning around.

Understanding these demand signals requires exactly the kind of real-time data synthesis that AI platforms are designed to provide. Investors who can identify emerging AI-driven demand corridors before they become consensus trades will capture the most attractive entry points.

Asset Management and Portfolio Optimization

The value of AI in commercial real estate does not end at acquisition. Post-close asset management is equally transformed. AI systems can monitor lease expirations, track tenant financial health, benchmark operating expenses against peer properties, and generate hold-versus-sell analyses on a continuous basis rather than as a periodic exercise. This shifts asset management from a reactive discipline — responding to problems as they emerge — to a proactive one, where risks are identified and addressed before they affect returns.

Natural Language Processing in Lease Abstraction

One particularly impactful application is natural language processing applied to lease abstraction. Extracting critical economic and legal terms from complex commercial leases has traditionally required hours of attorney or paralegal time per document. NLP models can now perform this task in minutes with high accuracy, dramatically reducing due diligence costs and enabling investors to analyze larger deal volumes without proportional increases in overhead.

Interestingly, the same advances in real-time language processing that are enabling faster lease abstraction and document analysis in CRE are also powering broader AI applications. Researchers exploring fast-response text-to-speech engines for real-time AI companions are developing the underlying language model infrastructure that increasingly informs how AI platforms process and communicate complex information — a convergence that will continue to benefit enterprise AI tools across industries, including real estate.

NOAL: Bringing Institutional-Grade AI to CRE Professionals

Among the platforms emerging to meet this moment, NOAL stands out for its focused approach to the commercial real estate investment workflow. Noal is an AI-powered commercial real estate platform built specifically around the disciplines that matter most to CRE professionals: underwriting, investment analysis, deal evaluation, financial modeling, and asset management. Rather than offering a generic AI assistant layered on top of existing tools, NOAL is purpose-built for the specific analytical demands of the CRE industry, integrating the data inputs and output formats that investment teams actually use.

This specialization matters. Generic AI tools require significant customization and prompt engineering to produce outputs that meet the standards of institutional real estate analysis. A platform designed from the ground up for CRE workflows can deliver accurate, actionable results with far less friction, allowing teams to move faster without sacrificing analytical rigor.

The Competitive Imperative

The adoption curve for AI in commercial real estate is steepening. Early adopters are already reporting meaningful improvements in deal throughput, underwriting accuracy, and portfolio performance monitoring. As these advantages compound over time — better deals sourced, fewer errors in underwriting, more proactive asset management — the gap between AI-enabled firms and those still relying on legacy processes will widen.

For investment managers, developers, and brokers, the question is no longer whether AI will transform commercial real estate. It already is. The question is whether your organization will be positioned to capture the benefits of that transformation or find itself competing at a structural disadvantage against peers who moved earlier.

Conclusion

Artificial intelligence is not a distant future for commercial real estate — it is the present competitive landscape. From accelerating underwriting timelines and enabling richer scenario analysis to identifying AI-driven demand trends and optimizing portfolio performance, the applications are concrete, measurable, and growing. Platforms purpose-built for the CRE investment workflow are making institutional-grade analytical capabilities accessible to a broader range of market participants, leveling a playing field that has historically favored the largest and most resource-rich firms. For professionals serious about staying ahead in this environment, understanding and adopting the right AI tools is no longer optional — it is a strategic necessity.

Daily writing prompt
What’s a place you visited that felt like home?

Roosh Ventures, Sergey Tokarev’s Venture Fund, Entered the Prestigious Sifted Ranking

Sergey Tokarev’s Ukrainian investment fund Roosh Ventures entered the top 50 investors in France and the Benelux

Investment fund Roosh Ventures, which invests in technology startups in different regions of the world, became the first and only Ukrainian representative in the Sifted ranking. It took 43rd place in the top 50 lenders and investors in France, Belgium, the Netherlands and Luxembourg. In addition, three portfolio companies — Folk, Alma and Gladia — entered the list of the region’s fastest-growing startups. This was announced by Sergey Tokarev, a co-founder of Roosh Ventures, investor and technology entrepreneur.

Sifted Ranking: How the Ukrainian Venture Fund Achieved This

Leading European media outlet Sifted specialises in startups and technology businesses, analyses the venture capital market, compiles authoritative rankings and covers news. When evaluating companies, it considers a set of criteria, including the quality of the formed portfolio, the player’s impact on the development of the local ecosystem and the intensity of completed deals.

Three Roosh Ventures portfolio companies were recognised by Sifted:

  • Folk creates a CRM platform that gives people, rather than algorithms, control over business relationships.
  • Alma is scaling a powerful payment system with a focus on the model of responsible consumption.
  • Gladia develops infrastructure based on artificial intelligence for speech analysis and transcription.

This selection, which brings together innovations from different sectors, demonstrates the fund’s overall investment priorities.

“The appearance of a venture fund from Ukraine among the best demonstrates that the place of registration is no longer a determining factor for the scaling and competitiveness of venture capital. Previously, most positions were allocated to local European funds, so the presence of a Ukrainian player on this list makes it stand out against the general background,” says Sergey Tokarev.

The entrepreneur is confident that this result became possible precisely because of Roosh Ventures’ approach to selecting projects.

“What happened is not a coincidence. It cannot be called an ordinary line in a ranking. By entering the top 50 investors in France and the Benelux, we proved that Ukrainian venture funds are already playing in the top league among European countries,” says co-founder of Roosh Ventures.

The result of the Sifted ranking, which included Roosh Ventures and three of its portfolio companies, is becoming part of a broader trend in which Ukrainian investment and technology teams are increasingly becoming competitors to Western players. For an investor who operates at the intersection of business, technology and social impact, the presence of the venture fund in a European ranking is proof of the right strategy, not an end in itself.

Daily writing prompt
If you had to switch lives with a fictional character for a week, who would you choose?

Top 5 Fast-Response TTS Engines for Real-Time AI Companions

You want a voice that responds like a real person, not a pause between sentences. This article helps you pick TTS engines designed for ultra-low latency so your virtual companion talks back fast and stays in sync with conversation. You’ll learn which platforms give the quickest, most natural real-time responses and why that matters for believability and user engagement.

You’ll see practical guidance on performance, setup, and integration so you can match an engine to your system and use case. Expect clear comparisons of modern real-time TTS options and the key factors you must check before plugging a voice into a live AI companion.

1) Inworld Realtime TTS-2

You get a voice model built for real-time back-and-forth conversation. Realtime TTS-2 listens to prior audio, senses tone and pacing, and uses that context to shape its next reply.

Latency focuses on fast response; reported median time-to-first-audio targets under 200 ms for many use cases. That low delay helps your virtual companion sound more natural during live exchanges.

The model supports a single, consistent voice identity across many languages, which keeps your character stable as conversations switch tongues. It also offers emotional control so you can set the desired expressiveness for different scenes.

Realtime TTS-2 comes as a research preview and includes lower-cost variants for production trade-offs. Use it when you need tight timing and expressive speech in interactive apps like games or chat agents.

2) Kokoro TTS

Kokoro TTS gives you self-hosted, low-latency speech that fits real-time companions. You can stream audio as text is generated, so voices start before a sentence finishes.

You control deployment and costs because Kokoro runs locally or on your servers. That makes it easier to meet privacy rules and tune performance for your user base.

Latency often falls under conversational thresholds when you optimize networking and model size. Kokoro also supports multiple voices and basic cloning, so you can craft distinct personalities for your companion.

Integration stays simple with browser and server SDKs that focus on streaming APIs. You will need some ops work to scale reliably, but the tradeoff is predictable latency and full data control.

3) MeloTTS (MyShell)

MeloTTS runs well on CPUs, so you can get real-time voice with modest hardware. You will notice low latency even on laptops and small servers, which helps keep conversations feeling natural.

It supports multiple languages and several English accents, so you can match the voice to your companion’s persona. You can also fine-tune voices on a laptop within a short time, letting you create custom tones and speech patterns.

The library balances speed and quality without needing large GPU clusters. You can integrate it into chat systems or apps where quick turn-taking matters most.

Documentation and open-source code make it practical to test and adapt. If you need a responsive, multi-lingual TTS for a virtual friend or agent, MeloTTS is a strong option.

4) Coqui TTS 

Coqui TTS offers a solid path for low-latency, self-hosted speech. You can run its Realtime server to stream generated audio with latencies often under 200 ms on good hardware.

Set up requires installing the coqui-tts package and starting the realtime API. You will configure a model, audio codec, and streaming backend so your app receives audio frames as they are produced.

Resource needs vary by model. Lightweight voices run well on a modern CPU, while higher-quality models benefit from a GPU to keep latency low. Monitor CPU, memory, and audio buffer sizes to avoid glitches.

Coqui supports multiple languages and voice styles, and you can fine-tune or add custom voices if you need unique characters. Use its WebSocket or HTTP streaming endpoints to integrate with chat clients and voice agents.

5) Orpheus Realtime TTS

Orpheus Realtime TTS focuses on low-latency streaming so your app responds quickly. You get audio that starts playing while the model keeps generating, cutting perceptible wait time.

The system supports modular inference, separating the language model from the audio decoder. This lets you scale and tune each part independently for better throughput and lower time-to-first-byte.

Implementations show Orpheus can run hundreds of concurrent streams per high-end GPU when properly optimized. You will still need fast hardware and quantized models to hit the best real-time numbers.

Documentation and examples include Flask-based servers and browser clients for streaming. Use those patterns to integrate Orpheus into chatbots, virtual companions, or interactive agents with minimal engineering guesswork.

Essential Criteria for Ultra-Low Latency TTS

You need measurable latency targets, predictable network behavior, and a deployment plan that scales with real user load. Focus on precise metrics, end-to-end timing, and infrastructure choices that keep response time under your conversational threshold.

Latency Benchmarks Explained

Measure latency end-to-end, not just model synthesis time. Use TTFA (time-to-first-audio), P50/P95/P99 percentiles, and IQR to capture typical and tail behavior. Track P50 to know the usual experience and P95/P99 to avoid jarring delays for users.

Run tests with realistic payloads: average utterance length, codec and sample rate, and any voice-cloning warm starts. Include cold-start and warmed-up runs to show how caching or model priming changes numbers. Log both server-side timestamps and client arrival to find network vs. server contributions.

Compare services by consistent methodology: same text, same audio config, identical connection type (WebSocket or gRPC). Report units in milliseconds and present distributions, not single averages, so you can enforce SLAs and set reliable latency budgets.

Impact of Network and Hardware

Network RTT and jitter often dominate small synthesis times. Test on representative paths: mobile cellular, Wi‑Fi, and wired datacenter links. Measure packet loss impact and use UDP-friendly streaming where possible to reduce head-of-line blocking.

Hardware matters: CPU vs GPU inference, model quantization, and batching strategies change latency. Favor single-utterance, low-batch inference for interactive agents. Use models optimized for streaming and low memory overhead to cut cold-start delays.

Place inference close to users with regional edge nodes or telco PoPs to lower RTT. Use WebSocket or bi-directional streaming to begin playback as tokens generate. Instrument network and host metrics so you can attribute latency to transport, queuing, or synthesis.

Scalability for High-Demand Applications

Design for concurrency, not just per-request speed. Measure latency under load with realistic RPS and conversation patterns, including spikes. Use load tests that simulate thousands of simultaneous short calls and measure P99 response times.

Autoscaling must act on queue depth and inference latency, not only CPU usage. Prefer stateless workers behind a fast load balancer so you can scale horizontally. Cache common phonetic segments or pre-render static phrases to reduce compute during peaks.

Plan for graceful degradation: lower sample rate, simpler voice model, or short-circuit to pre-recorded prompts when queues grow. Monitor costs alongside latency and set thresholds where you trade fidelity for responsiveness.

Integrating TTS Engines Into Real-Time Companion Systems

Plan for low-latency calls, stable audio codecs, and fallbacks for network issues. Prioritize batching, streaming, and local caching so your companion responds quickly and naturally.

Best Practices for API Integration

Choose WebSocket or gRPC streaming where available to get audio chunks as they’re generated. Use short-lived HTTP requests only for non-real-time tasks like voice model updates.

Authenticate with rotating tokens or short-lived keys to limit exposure. Implement retry with exponential backoff and jitter for transient failures. Track per-call metrics (request time, server processing, bytes sent) and log audio timestamps for debugging.

Use client-side buffering that plays partial audio while remaining segments arrive. Send context and voice parameters in the first frame to avoid extra round trips. For voice cloning or custom voices, upload and cache model artifacts ahead of time to avoid on-demand model loading.

Optimizing End-to-End Response Times

Measure time across each hop: client queue → network RTT → TTS server inference → audio transfer → client decode/play. Instrument each stage so you can spot the slow link quickly.

Reduce payload size by sending concise prompts and removing unnecessary metadata. Prefer compressed codecs (Opus) and stream small audio frames (20–40 ms) for smooth playback. Co-locate servers near users or use edge TTS nodes to cut RTT.

Enable incremental synthesis: start playback on first audio chunk instead of waiting for full output. If using voice clon­ing or high-quality neural models, prepare a lower-latency backup voice to use under load. Set firm time budgets per utterance and fail gracefully with brief text or cached clips when budgets exceed limits.

Handling Multilingual Voice Requirements

Detect user language early using a lightweight language ID model on the client or an early server pass. Route requests to the TTS voice model that matches language + locale to avoid mispronunciations.

Maintain a table of supported language codes, voice variants, and expected latency for each voice. Use phoneme or SSML input for tricky names and borrowings to keep pronunciation stable across languages.

For mixed-language utterances, split the text into segments by language and request streaming synthesis per segment to preserve prosody. Cache commonly used multilingual phrases and their rendered audio to avoid repeated synthesis. When quality or latency differs by language, fall back to a neutral voice and notify logs for future tuning.

Daily writing prompt
What’s the best and worst airport you’ve been to?

Touchstone Digital Solutions Unveils Digital Donor Wall Platform, Redefining Philanthropic Recognition for Universities, Schools and Nonprofits

New interactive, cloud-based donor recognition systems replace static engraved plaques with dynamic storytelling, real-time updates and measurable fundraising impact

BEDFORD, NH – August, 2026 — Touchstone Digital Solutions, a provider of digital donor recognition technology, today announced the expansion of its Digital Donor Walls platform, a cloud based system designed to help universities, schools and nonprofit organizations modernize the way they honor their most generous supporters.

For decades, institutions have relied on physical, engraved donor walls to acknowledge contributions. According to the company, these static displays are increasingly unable to capture the scale of modern giving campaigns or convey the ongoing impact of donor generosity . Touchstone’s Digital Donor Wall addresses this gap by combining high resolution visuals, animation and storytelling elements with a secure, easy to manage software backend.

A Shift From Static Plaques to Dynamic Storytelling

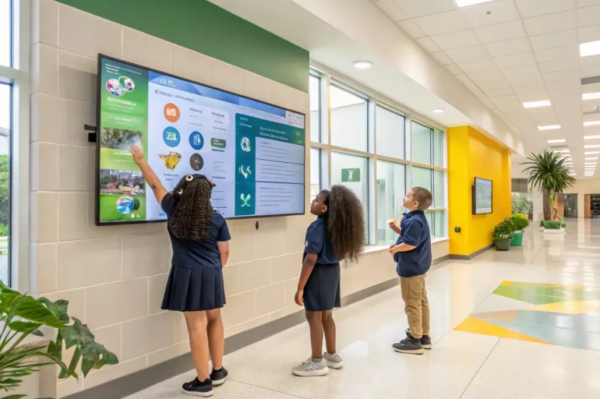
The Digital Donor Wall system allows organizations to move beyond simple name listings. Institutions can showcase donor names, giving levels and personalized messages in animated layouts, while integrating video, photo galleries and infographics that demonstrate the tangible outcomes of contributions . Visitors are able to interact with the displays, filtering by campaign or giving to society and exploring individual donor stories, creating a more immersive recognition experience than traditional signage allows.

A key feature of the platform is real-time content management. Donor services teams can add new names, launch new campaigns or update information instantly through a secure online dashboard, without requiring technical expertise. Touchstone positions this as a direct alternative to the recurring costs associated with physical re-engraving, which the company notes can exceed 1,500 US dollars each time a donor list requires updating or an additional panel is needed.

“We view donor recognition not as a static transaction but as an ongoing relationship,” said a Touchstone Digital Solutions spokesperson. “Our platform gives institutions the ability to keep that relationship alive visually, updating instantly as their community and their campaigns grow, rather than freezing recognition in wood or bronze the moment it is installed” .

Scalable Across Sectors

The company said the platform has been built to scale from small installations of roughly 100 donors to large, multi-screen deployments recognizing more than 100,000 supporters, making it applicable across a wide range of institutional sizes and missions.

In higher education, the system is designed to recognize alumni, faculty and benefactors, celebrate scholarship recipients, mark facility dedications and present historical timelines of institutional giving, typically installed in student unions, alumni centers or library entrances. Hospitals and health organizations can use the walls to highlight patient success stories, showcase donor-funded medical technology and recognize foundation leadership societies, often in main lobbies or waiting areas. Schools can apply the technology to recognize PTA members, capital campaign donors and local business partners during events such as parent-teacher nights and open houses .

A third party industry observer said the shift reflects a broader trend in institutional communications. “Donor recognition has traditionally been treated as a fixed cost buried in a capital project budget,” the spokesperson said. “What we’re seeing now is organizations treating digital recognition wall displays as active engagement tools that can be measured, updated and tied directly to future fundraising performance, rather than a one time installation that becomes outdated within a few years”.

Positioned as a Long term Investment

Touchstone frames the Digital Donor Wall as a long-term financial and stewardship asset rather than a one-time capital expense. The company’s investment materials cite comparative cost scenarios in which digital solutions offer meaningful long term savings relative to traditional engraving once repeated updates, additions and panel expansions are factored in over time. Beyond cost, the company argues that visible, dynamic displays of community impact serve as a persuasive tool for prospective donors evaluating whether to contribute to an organization.

The company’s implementation process follows five stages: discovery and strategy sessions to understand an organization’s goals and brand; custom interface design; development and integration with existing donor databases; hardware deployment including large format screens and touchscreen kiosks with staff training; and ongoing support to keep content current. Touchstone said its US-based support team remains engaged with client organizations after launch to ensure displays continue to perform and evolve alongside institutional needs.

The Digital Donor Wall platform is available now to universities, colleges, K-12 schools and mission driven nonprofit organizations across the United States seeking to modernize donor stewardship and strengthen long-term fundraising relationships.

About Touchstone Digital Solutions

Touchstone Digital Solutions designs and deploys custom digital donor recognition systems for universities, schools and nonprofit organizations across the United States. The company combines interactive display technology, cloud based content management software and dedicated US based support to help mission driven institutions transform static donor recognition into dynamic, ongoing storytelling that strengthens community engagement and supports long-term fundraising success.

Media Contact

Touchstone Digital Solutions

8 Powder Hill Road, Bedford, NH 03110

Phone: (603) 361-7541

Email: info@touchstone-ds.com
Website: https://touchstone-ds.com/

Daily writing prompt
What’s the best thing you’ve ever found randomly on the street?

How to Choose a Server for a Telegram Bot Without Paying for Unused Resources

Choosing a VPS for a Telegram bot based solely on CPU cores and RAM often leads to unnecessary costs or performance problems. Some projects run for months on oversized servers that never use more than a small fraction of their resources, while others outgrow entry-level plans soon after CRM integrations, databases, AI features, or background tasks are introduced.

For Telegram bots, user count is a poor indicator of server requirements. A bot with thousands of subscribers may generate very little load, while another serving only a few dozen active users can require significantly more resources because of databases, AI services, document processing, task queues, or external APIs.

The real factor is workload, not audience size. Every user message may trigger database queries, file processing, background jobs, and multiple API requests, all of which determine how much CPU, memory, storage, and network capacity the project actually needs.

The best way to choose a VPS is to understand what happens after a message reaches the bot. This approach helps avoid paying for unused resources while leaving enough capacity for future growth.

Why User Count Is a Poor Way to Choose a VPS for a Telegram Bot

One of the most common questions is: I have 500 users—how much CPU and RAM do I need? For Telegram bots, the answer depends far less on user numbers than on what happens after each message reaches the application.

Support teams regularly see bots with only 80–100 active users generating more load than informational services with several thousand subscribers. An informational bot typically retrieves prepared data and returns a response with minimal database activity. An AI-powered or CRM-integrated bot may store conversation history, process documents, update customer records, manage task queues, and communicate with multiple external APIs for every user request.

The same principle applies to e-commerce bots, where product searches, stock checks, shopping carts, and payment processing generate far more work than audience size alone suggests.

Bot TypeTypical Load
Informational botLow
CRM and lead management botMedium
E-commerce botMedium to High
AI-powered botHigh

For Telegram bots, workload is a far better indicator of infrastructure requirements than user count. Database activity, file processing, AI services, task queues, and external integrations determine how much CPU, memory, storage, and network capacity a project actually needs.

How to Estimate the Load a Telegram Bot Will Generate

When choosing a VPS, many people estimate future load by the number of users. A more useful question is: what happens after a user sends a message? The answer determines the server requirements.

A simple informational bot usually retrieves prepared data and returns a response. Even thousands of requests per day may generate little load because each interaction requires only a few database queries or API calls.

The situation changes when the bot performs additional work. A lead-generation or CRM bot may verify a user, create or update records, store interaction history, synchronise data, and notify staff after every message. AI-powered bots increase the workload further by processing uploaded files, managing conversation history, communicating with external AI services, and running background tasks. File-processing bots place additional pressure on storage because every document, image, or voice message must be stored and processed.

Project TypeMain Resource Under Load
Informational botNetwork and application layer
CRM and lead management botDatabase and APIs
E-commerce botDatabase and external services
File-processing botStorage and network
AI-powered botMemory, task queues, database, and APIs

The easiest way to estimate VPS requirements is to map everything that happens after a single user message. The more databases, APIs, AI services, background jobs, and file operations involved, the more resources the bot will require, regardless of how many users it serves.

How to Calculate Minimum Resources for a Telegram Bot

Trying to choose a server for the next several years usually leads to one of two mistakes: paying for resources that remain unused or running out of capacity soon after launch. A more practical approach is to size the VPS for current requirements while leaving 30–50% headroom for future growth.

Bot TypevCPURAMNVMe Storage
Informational bot, notifications11–2 GB20–30 GB
CRM, lead management, database-driven bot2–34–6 GB30–50 GB
E-commerce bot3–44–8 GB40–60 GB
AI bot, document processing, task queues4+8–12+ GB50+ GB

Support engineers at Era.Host regularly see projects that begin with a simple notification bot and later grow into CRM- or AI-powered platforms. In most cases, the initial VPS remains sufficient longer than expected when resources are chosen according to the actual workload rather than projected user numbers.

Simple Telegram bots usually require modest resources, making VPS stability and fast NVMe storage more important than additional CPU cores. As databases, CRM integrations, and message history grow, memory often becomes the first limiting factor. AI-powered bots place further demands on CPU, RAM, and background processing, while file-heavy applications depend heavily on storage performance.

Rather than sizing a VPS by user count, estimate the workload created by each message. A balanced configuration with room for growth and the ability to scale is usually a safer choice than trying to predict the perfect server years in advance.

Choosing the Right Virtualisation Type for a Telegram Bot

When choosing a VPS, most people compare CPU cores, memory, and storage while paying little attention to the underlying virtualisation technology. For production Telegram bots, however, consistent access to resources is often more important than their maximum amount.

Support engineers regularly investigate bots that become slower during busy periods even though CPU utilisation remains low and the application shows no errors. In many cases, the problem is not the bot itself but resource contention between virtual environments on the same physical host.

Virtualisation TypeGuaranteed ResourcesSuitable for Telegram Bots
KVMYesYes
OpenVZ / LXCPartialSuitable for simple projects
Shared HostingNoNot recommended

KVM provides an isolated virtual machine with dedicated memory and predictable performance, making it well suited to Telegram bots that run continuously and rely on databases, task queues, Redis, PostgreSQL, AI services, or background processing.

As workloads grow, predictable resource allocation becomes increasingly important. Choosing a VPS should therefore involve more than comparing CPU cores and RAM. For most production bots, guaranteed resources and stable performance are the main reasons KVM remains the preferred option.

How to Tell When Storage Performance Is Holding Back Your Telegram Bot

When investigating a slow Telegram bot, most owners start by checking CPU and memory usage. If CPU utilisation remains low, the problem is often assumed to be the application itself. In many cases, however, the real bottleneck is storage performance.

Support engineers regularly diagnose bots where CPU usage stays below 20%, yet response times reach 2–4 seconds because the database spends most of its time waiting for read and write operations.

Database-driven bots become increasingly dependent on storage as message history, customer records, logs, and other operational data grow. Queries that once completed in a few milliseconds may gradually take much longer, reducing overall responsiveness even though CPU and memory remain largely idle.

On Linux, storage bottlenecks can often be identified with:

iostat -x 1
iotop

If disk activity remains high while CPU utilisation stays low, storage I/O is likely the limiting factor.

Fast NVMe storage is particularly important for Telegram bots because databases such as SQLite and PostgreSQL perform large numbers of small read and write operations. Redis may also generate disk activity during snapshots and recovery.

When CPU utilisation is low but response times continue to increase, upgrading the processor is unlikely to help. Faster NVMe storage, database optimisation, or improved caching usually delivers a much greater improvement.

How Server Location Affects Telegram Bot Performance

When choosing a VPS, most people compare CPU, memory, and storage while overlooking the server’s physical location. As a Telegram bot grows, however, network latency often becomes just as important as computing power.

Support teams regularly see projects where upgrading CPU or RAM has little effect because most of the response time is spent communicating with Telegram, databases, CRM platforms, AI services, payment gateways, and other external systems.

Every user request may trigger multiple network operations. A message is received from Telegram, processed by the application, and then followed by additional requests to databases, APIs, or AI platforms before a response is returned. Even small delays accumulate when several external services are involved.

A latency difference of 20–30 ms versus 150–200 ms may seem minor for a single request, but it becomes noticeable when every interaction requires multiple sequential API calls. This is especially true for AI-powered bots, where communication with Telegram, AI services, databases, and file storage often takes longer than the processing itself.

For that reason, Telegram bot performance depends not only on server resources but also on network quality, routing, and the location of the data centre.

Why Many Telegram Bots Are Hosted in Europe

For international projects, European data centres often provide the best balance between connectivity and latency. Strong links to major cloud platforms, AI services, payment providers, and international networks help deliver more predictable response times.

Many projects choose locations such as Estonia, Germany, or the Netherlands because of their stable routing and high-quality connectivity. Support engineers regularly see bots become more responsive after moving from local hosting to a European data centre, even without changing CPU or memory. The improvement usually comes from lower network latency and more efficient communication with Telegram APIs and external services.

For bots that rely on AI platforms, CRM systems, payment gateways, and users across multiple countries, data centre location can influence performance just as much as server hardware.

How to Choose a Telegram Bot Server with Room for Growth

One of the most common mistakes is choosing a VPS based on where the project might be several years from now. Some owners pay for resources that remain largely unused, while others start with the smallest plan and face upgrades after adding databases, CRM integrations, background jobs, or AI features.

A better approach is to size the server for current requirements while leaving room for near-term growth.

For most Telegram bots, a practical starting point is:

Project TypeRecommended Configuration
Notifications and simple bots1–2 vCPUs, 1–2 GB RAM
CRM and database-driven bots2 vCPUs, 2–4 GB RAM
AI, document processing, task queues4+ vCPUs, 4–8 GB RAM

When choosing a provider, make sure CPU, RAM, and storage can be upgraded without migrating the project. Memory is usually the first resource to become a limitation, while CPU and storage requirements often increase later as workloads grow.

A practical strategy is to leave 30–50% spare capacity and scale resources only when monitoring shows they are actually needed. This avoids paying for unused infrastructure while allowing the project to grow without disruptive migrations.

Common Mistakes When Choosing a Server for a Telegram Bot

Many Telegram bot performance issues begin long before traffic increases. They often result from choosing the wrong VPS rather than from problems in the application itself.

Mistake #1: Not Allocating Enough RAM

As databases, CRM integrations, Redis, and background jobs grow, memory often becomes the first limiting resource. Servers begin using swap, response times increase, and owners mistakenly blame the application instead of insufficient RAM.

Mistake #2: Choosing Storage Based Only on Capacity

Storage performance matters far more than disk size. As databases, conversation history, and file processing grow, slow storage can become a bottleneck even when CPU and memory remain largely unused.

Mistake #3: Choosing a VPS Solely on Price

A low-cost VPS may be adequate for testing, but once a bot supports customer enquiries, orders, or business automation, downtime can cost far more than the savings on hosting.

Mistake #4: Focusing Only on CPU

Many Telegram bots are limited by database performance, storage, memory, or network latency rather than processing power. Adding CPU cores rarely solves these problems on its own.

Mistake #5: Underestimating Database Growth

Message history, logs, analytics, and integration data steadily increase database activity. Infrastructure that performs well at launch may become a bottleneck as stored data grows.

Mistake #6: Ignoring Future Growth

A simple notification bot can quickly evolve into a platform with CRM integrations, AI features, document processing, and background tasks. Choosing a VPS that can be upgraded without migration makes future growth much easier.

Most infrastructure problems are caused not by insufficient CPU, but by focusing on a single specification instead of considering memory, storage, databases, network quality, and scalability together.

Daily writing prompt
If you could relive one day from your past, which day would it be and why?

Essential Strategies for Expanding a Service-Based Business into International Markets

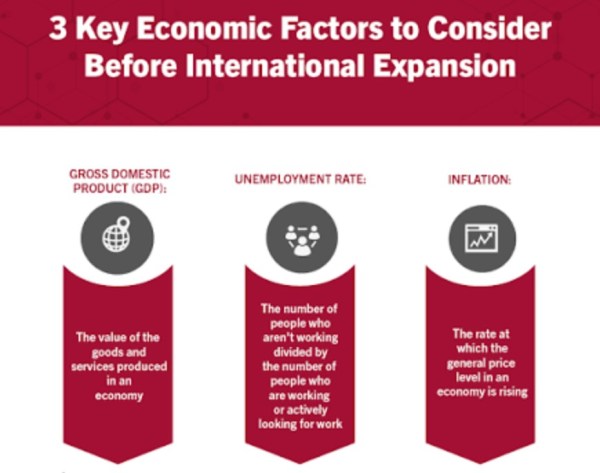
The global economy is undergoing a massive structural shift. For decades, international trade was dominated by the export and import of physical goods. Today, service-based businesses are taking centre stage, driven by rapid digitalisation and an increasingly interconnected global workforce. The widespread adoption of remote work infrastructure has normalised cross-border service delivery, allowing consultancies, agencies, and tech firms to seamlessly serve clients thousands of miles away. According to the McKinsey Global Institute, international trade in services, intellectual property, and education grew twice as fast as trade in physical goods between 2010 and 2019. This incredible growth presents a highly lucrative opportunity for professional, technical, and digital service providers looking to expand their footprint abroad. However, crossing borders as a service firm requires an entirely different approach compared to traditional manufacturing.

Navigating Regulatory and Compliance Challenges

Unlike product manufacturers who primarily deal with customs duties and tariffs, service-based businesses face unique non-tariff barriers in foreign markets. These can include strict data localisation laws, mandates for local commercial presence, and restrictive professional licensing requirements. Because services are inherently intangible, transferring a successful domestic service model across borders requires significant local adaptation. Furthermore, intellectual property protection becomes far more complex when operating in jurisdictions with differing legal frameworks. Securing trademarks, copyrights, and proprietary methodologies must be an immediate priority to prevent unwanted infringement.

Expanding into high-growth regions like the Asia-Pacific demands careful alignment with regional labour laws and foreign ownership limits. In many emerging markets, soft-service industries such as consulting, accounting, and legal advisory face caps on majority foreign ownership. This frequently forces firms to rely on complex joint ventures or strategic partnerships to remain compliant. To overcome these hurdles, business owners must develop a robust market entry strategy for service firms that carefully assesses local corporate structures, tax compliance, and intellectual property protection before committing capital. Proper planning early on helps to mitigate risks, prevents costly operational delays, and ensures that the chosen legal entity is optimised for future growth.

Building a Foundation for Cross-Cultural Operations

Establishing a successful service business in a new country is heavily reliant on human capital. Your team will be the face of your brand, and their ability to navigate local business etiquette and cultural nuances will directly dictate your success. Delivering a service is a highly interactive process, meaning consumer expectations, negotiation styles, and trust-building exercises can vary wildly from one region to the next. What might be considered efficient and direct communication in London could be perceived as overly aggressive in Tokyo or Hanoi.

To thrive internationally, founders must focus on effective cross-cultural communication and strong leadership skills. Finding the right talent often means competing in unfamiliar labour markets while simultaneously trying to instil your core company values into a newly formed foreign team. Exploring comprehensive business and management resources can help entrepreneurs master the foundational skills needed to build dynamic, multicultural teams. By investing time into understanding local workplace dynamics, service firms can reduce turnover, improve client satisfaction, and ensure their overseas operations run smoothly and efficiently.

Key Steps for Incremental Global Expansion

Academic literature often points to the Uppsala internationalisation model for service firms, which suggests that businesses should use an incremental market entry approach. Rather than attempting a massive, all-at-once global launch, service providers should gradually expand to mitigate risks while learning local regulations through practical, experiential knowledge. Taking measured steps allows firms to adapt their operational blueprints without risking catastrophic financial losses.

When preparing for international expansion, consider following these essential steps:

  • Conduct rigorous market research: Identify regions with a growing demand for your specific expertise. For instance, the expanding middle class in Southeast Asia is driving unprecedented demand for professional and B2B services, making it a prime target for ambitious firms.
  • Start with a light footprint: Before setting up a full subsidiary, consider exporting your services digitally or partnering with local agencies to test the market waters. This approach helps validate demand before committing to substantial fixed costs.
  • Adapt your service delivery: Customise your offerings to meet local consumer preferences, languages, and pricing sensitivities. Localisation should extend beyond mere translation to encompass the entire customer journey and service philosophy.
  • Monitor legal and financial compliance: Engage with local legal counsel and accounting professionals early in the process. Navigating foreign tax obligations and employment laws is critical to maintaining good standing with local authorities.
  • Leverage automation: Use digital tools like robotic process automation to standardise administrative operations across multiple jurisdictions, keeping overhead costs manageable as you scale your operations globally.

Conclusion

Taking a service-based business international is a complex but highly rewarding endeavour. While the lack of physical inventory simplifies some aspects of global trade, the regulatory and cultural challenges require meticulous preparation. By adopting an incremental approach, securing the right compliance structures, and prioritising cross-cultural team building, service firms can successfully tap into the booming global services market. With the right strategy and a willingness to adapt, your business can build a resilient, profitable presence on the global stage.

Daily writing prompt
What’s something you used to worry about but don’t anymore?

How a Specialist High-Risk Acquirer Actually Works: Mechanics, Costs, and Where the Model Fits

6a70808ac507e.webp

A subscription software company with a 1.2% dispute rate receives a termination notice from its payment processor on a Tuesday morning. No prior warning. No appeal window. By Thursday, its checkout page is dead. The business had been operating on a pooled aggregator account — the kind that onboards in minutes — and when its dispute ratio crossed an internal threshold, the automated system acted faster than any human could intervene.

This is not an edge case. It is the structural consequence of how payment facilitators are built. The architecture that makes instant onboarding possible is the same architecture that makes instant termination possible. Understanding that trade-off is the starting point for any serious evaluation of acquiring options for merchants whose business models carry elevated chargeback exposure.

Market Context: Why Acquirer Appetite Is Tightening

Visa’s VAMP (Visa Acquirer Monitoring Program) framework places the compliance burden squarely on acquiring banks, not just on individual merchants. When a bank’s portfolio dispute ratio breaches program thresholds, the bank faces fines and, in extreme cases, loss of principal membership. The rational response for a mainstream acquirer is portfolio pruning: exit the MCCs that statistically generate the most disputes before the ratio triggers a monitoring designation.

The result is a bifurcated market. Merchants with clean, low-ticket, low-dispute profiles are well served by aggregators and mainstream banks. Merchants in subscription billing, telehealth, direct-marketing, travel, and online education — categories where delivery lag, recurring charges, and cross-border exposure structurally elevate dispute probability — find mainstream acquiring increasingly unavailable, regardless of their individual dispute history. That gap is the commercial rationale for the specialist high-risk acquirer category. Global payments infrastructure investment and digital fraud trends confirm that acquirer-side risk management is intensifying, not relaxing, as fraud tooling and network monitoring programs grow more sophisticated.

Five Mechanics That Define the Specialist Acquiring Model

1. Dedicated MID Architecture Versus Pooled Sub-Merchant Accounts

Stripe, Square, and PayPal operate as payment facilitators. Each merchant is a sub-merchant under a single master MID. That structure is why onboarding takes minutes: the facilitator absorbs the compliance burden and underwrites the portfolio in aggregate. The trade-off is that the portfolio is scored in aggregate too. A dispute spike from an unrelated sub-merchant can trigger risk controls that affect every account on the master MID, including yours. Termination, holds, and reserve increases can propagate across the pool without the individual merchant having done anything wrong.

A specialist acquirer boards each merchant on its own dedicated MID. The merchant’s dispute ratio is measured in isolation. Another merchant’s bad month does not re-score your account. This is the foundational structural difference between the two models, and it matters most precisely when dispute pressure is highest — which is when the protection is most needed.

Why it matters: A dedicated MID means your account’s standing is determined by your own performance history, not by the aggregate behavior of thousands of unrelated businesses.

2. Human Underwriting and What Reviewers Actually Read

Automated underwriting systems score applications against static rule sets. A business model that sits outside those rules — a telehealth platform with variable ticket sizes, a subscription education service with a free-trial funnel — may be declined not because it is genuinely high-risk but because the model does not pattern-match to the system’s training data. There is no appeal because there is no reviewer.

Specialist acquirers assign a named underwriter to each application. That underwriter reads the business model, the refund policy, the marketing copy, the processing history, and the dispute breakdown. The review is qualitative, not just quantitative. 2Accept states that its underwriting review is completed within one business hour of receiving a complete file, with full approval averaging 48 hours. The clock starts on a complete file — EIN, articles of incorporation, voided check, three months of bank statements, three months of processing statements where they exist, government-issued photo ID, and a live storefront URL. Incomplete submissions restart the clock.

Why it matters: A human reviewer can distinguish between a structurally sound business with an unusual model and a genuinely problematic one. An algorithm cannot.

3. Risk Management Stack: Dispute Alerts, Fraud Scoring, and Liability Shift

Dispute management in high-risk acquiring is not a single tool; it is a layered stack. Ethoca (Mastercard-owned) and Verifi CDRN (Visa-owned) are dispute alert networks that notify the merchant before a chargeback is formally filed, allowing a refund to be issued and the dispute to be resolved without a chargeback hitting the ratio. Running only one network leaves a significant share of volume — either Visa or Mastercard — without alert coverage. Both networks together provide the broadest possible pre-chargeback interception.

Real-time fraud scoring tools such as Kount, Sift, and NoFraud assess transaction risk at the point of authorization. 3DS 2.0 authentication shifts liability for unauthorized transaction claims to the issuer. It is important to be precise about what 3DS does and does not do: it covers unauthorized-transaction disputes only. It provides no protection against friendly fraud — where a cardholder disputes a transaction they authorized — or item-not-as-described claims. Merchants who believe 3DS eliminates chargeback exposure are misinformed.

Why it matters: The combination of pre-chargeback alerts, real-time fraud scoring, and authentication-based liability shift addresses different dispute types; no single tool covers all of them.

4. Transparent Rate Structure and What the Numbers Actually Mean

Most specialist acquirers do not publish rates. Pricing is negotiated case by case, which makes comparison nearly impossible and gives the processor significant information asymmetry. 2Accept publishes a tiered rate card running from 2.89% at the low end to 4.95% at the top tier, with a rolling reserve of 0–10% of settled volume depending on processing history and risk profile. There are no long-term contracts and no early-termination fees, according to its published terms.

The transparency is genuinely unusual in this segment. But the numbers deserve honest context. A 4.95% processing rate is materially more expensive than the flat-rate pricing offered by aggregators — Stripe’s standard card rate is 2.9% plus $0.30, for example. For a merchant processing $500,000 annually, the difference between 2.9% and 4.95% is approximately $10,250 per year. That cost is the price of dedicated infrastructure, human underwriting, and the structural protections described above. Whether it is worth paying depends entirely on the merchant’s dispute exposure and the realistic alternative. For a merchant who cannot obtain mainstream acquiring at all, the comparison is not 2.9% versus 4.95%; it is 4.95% versus zero revenue. For a merchant who qualifies for mainstream acquiring, the aggregator is almost certainly the better economic choice.

When evaluating payment infrastructure for businesses with complex billing models, it is also worth considering how Layer 2 blockchain payment networks improve transaction scalability interact with card-network dispute rules, a topic that complements understanding payment gateway performance for non-traditional transaction types.

Why it matters: Published pricing removes information asymmetry, but the rate ceiling is genuinely high; the cost-benefit calculation only favors the specialist model when mainstream acquiring is unavailable or structurally unsuitable.

5. MCC-Level Specialization and Acquiring Bank Network

Acquiring appetite varies not just by merchant category but by MCC code within a category. A telehealth platform (MCC 8099) faces different chargeback thresholds, licensing requirements, and underwriting criteria than a subscription SaaS business (MCC 5734) or a direct-marketing catalogue merchant (MCC 5964). A specialist acquirer that has processed volume across these MCCs has historical dispute data, established relationships with sponsoring banks willing to hold those portfolios, and underwriters who understand the specific compliance requirements of each code.

The context paragraph for this section: 2Accept reports relationships with more than 40 acquiring banks — including Merrick Bank, BMO Harris, Citizens, The Bancorp, FFB Bank, SSB Bank, Wells Fargo, and PNC — and states that it processes more than $2 billion annually across its merchant portfolio. That bank network breadth matters because it enables MID placement with the institution whose risk appetite most closely matches a given merchant’s profile, and it supports multi-MID load balancing across two to five MIDs to distribute volume and reduce concentration risk.

Why it matters: MCC-level expertise and a broad bank network allow placement decisions to be made on fit, not just on availability.

Comparison: Specialist Acquirer Versus Aggregator

Dimension2AcceptPaymentCloudStripe / Square / PayPal 
MID structureDedicated MID per merchantDedicated MID per merchantPooled sub-merchant MID
Onboarding speed (low-risk merchant)48 hours (self-reported)24–72 hours (self-reported)Minutes — aggregators are faster here
Published rate cardYes, 2.89%–4.95%Not publicly publishedYes, flat-rate (lower ceiling)
Developer documentationStandard integration supportStandard integration supportAggregators lead on API docs and tooling
MATCH-listed applicantsReviewed case by caseReviewed case by caseTypically declined outright
Dispute alert coverageEthoca + Verifi CDRN (both networks)Varies by accountLimited or not offered
Rolling reserve0–10% of volumeVaries by accountPayPal: up to 21-day or 180-day holds possible

Note: Aggregator “instant approval” applies to low-risk merchants only; high-risk or flagged applications face the same review delays as specialist processors. All approval rates and approval times cited for any processor in this table are self-reported and have not been independently audited.

Where the Model Gets Expensive and Who It Is Not For

The specialist acquiring model carries real costs that deserve direct treatment, not a footnote.

Rate ceiling. A 4.95% processing rate is not a worst-case scenario to be avoided; it is the published top tier for merchants with elevated risk profiles. For high-volume merchants, the absolute cost difference against aggregator pricing is substantial. This is not a hidden fee — it is the stated price of the infrastructure — but it should be modeled explicitly before a decision is made.

Rolling reserve. A 0–10% rolling reserve means the processor holds back up to ten cents of every dollar settled. On $100,000 per month in volume, that is up to $10,000 per month in working capital that is not available to the business. Reserves are typically released on a rolling basis after a defined period, but the cash-flow impact during the reserve period is real and must be planned for.

US-only eligibility. The model requires a US-registered business entity, a US Social Security Number for the account signer, and US-issued government photo ID. International merchants, regardless of their processing volume or dispute history, are outside scope.

Document-heavy onboarding. The 48-hour approval window is conditional on a complete file. Merchants who cannot immediately produce three months of processing statements, articles of incorporation, and a live storefront URL will experience longer timelines. This is not a criticism — it is the nature of genuine underwriting — but it is a meaningful difference from a sign-up form.

Self-reported performance figures. The 98% approval rate and 48-hour average approval time are figures reported by the processor. They cannot be independently verified, and outcomes vary by MCC, volume, ticket size, and dispute history. A MATCH-listed applicant is reviewed case by case; approval is not guaranteed.

Who this is not for. A low-risk, low-ticket merchant with a clean dispute history and a straightforward business model — a retail SaaS tool, a low-volume consulting practice, a simple e-commerce store — is almost certainly better served by an aggregator. The onboarding is faster, the developer tooling is better documented, and the pricing is lower. The specialist model is designed for merchants who cannot access mainstream acquiring or who have been terminated from it. Using it when mainstream acquiring is available is paying a premium for infrastructure you do not need.

The Company Behind the Account

2Accept operates as an ISO/MSP (Independent Sales Organization / Member Service Provider) under KNET Systems Corp. ISO/MSP status means the company is registered with the card networks and operates under sponsorship agreements with acquiring banks rather than holding principal membership directly. Its stated sponsoring bank relationships include Merrick Bank, BMO Harris, Citizens, The Bancorp, FFB Bank, SSB Bank, Wells Fargo, and PNC. The company serves US-based merchants and requires a US-registered business entity and US-issued identification for the account signer. It reports processing more than $2 billion annually across its merchant portfolio.

The Question the Merchant Should Actually Be Asking

The framing that dominates most processor comparisons — who approves you fastest, who has the lowest rate — misses the operative question for a merchant with elevated dispute exposure. The operative question is: which acquiring structure is still processing my volume in eighteen months, and what does it cost to maintain that stability?

A pooled aggregator account that onboards in minutes and terminates in minutes is not a stable acquiring relationship for a subscription telehealth platform or a direct-marketing merchant with a 30-day refund window. A dedicated MID with human underwriting, dual dispute-alert coverage, and a named account contact is a different kind of infrastructure — slower to establish, more expensive to maintain, and considerably harder to lose without warning.

Whether that infrastructure is worth its cost depends on the merchant’s specific dispute profile, volume, and the realistic alternatives available to them. The specialist acquiring model is not universally superior; it is structurally appropriate for a specific category of merchant. Identifying whether you are in that category is the analysis that precedes any processor selection.

Sources and Further Reading

Visa VAMP (Visa Acquirer Monitoring Program) — Visa’s publicly documented acquirer-level dispute monitoring framework; supports the market-context section on portfolio-level compliance pressure.

Mastercard ECM/HECM (Excessive Chargeback Merchant / High Excessive Chargeback Merchant) program documentation — Mastercard’s published merchant-level chargeback monitoring thresholds; supports the discussion of network-level dispute ratio triggers.

Ethoca dispute alert network — Mastercard-owned pre-chargeback alert service; supports the risk-management stack section.

Verifi CDRN (Cardholder Dispute Resolution Network) — Visa-owned pre-chargeback alert service; supports the risk-management stack section.

EMVCo 3DS 2.0 specification — Published authentication standard; supports the liability-shift discussion and its stated limitations.

Stripe Prohibited and Restricted Businesses policy — Publicly available; supports the structural comparison of aggregator eligibility criteria.

PayPal User Agreement (holds and reserves provisions) — Publicly available; supports the 21-day and 180-day hold references in the comparison table.

KNET Systems Corp ISO/MSP registration — Card network registration records; supports the brand section.


Disclosure: Approval rates, approval times, and processing rates quoted for any processor in this article are self-reported by the respective processor; outcomes vary by volume, ticket size, dispute history, MCC, and individual underwriting review. Nothing in this article constitutes legal, financial, or compliance advice. This article contains a compensated link; the editorial content is the author’s independent analysis.

Daily writing prompt
What’s a quote that perfectly describes your outlook on life?

Cultivating Global Citizenship Through Holistic Education in Modern International Schools

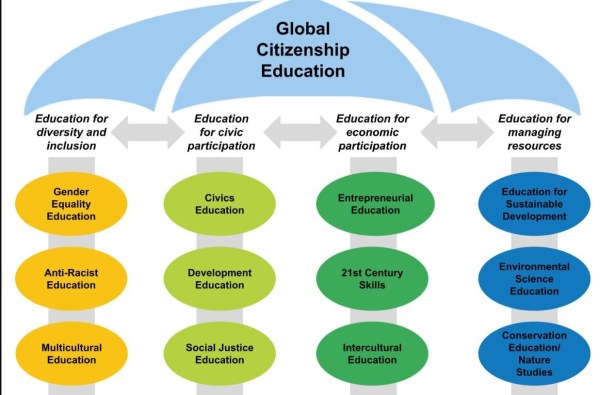
The landscape of modern schooling has transformed dramatically over the past decade. The 21st-century educational environment demands more than just rote learning and standardised test scores. Today, maintaining high standards of quality education requires institutions to look beyond traditional academic metrics and focus on the comprehensive development of students. As global conditions continue to evolve, the emphasis has shifted towards nurturing empathy, emotional intelligence, and a deep understanding of intercultural dynamics.

The Shift Towards Holistic Development

Modern educational literature frequently warns against superficial implementations of wellbeing strategies. Instead, experts urge schools to deeply integrate pastoral care into the core academic fabric. Post-pandemic priorities have definitively shifted in recent years. Parents are increasingly moving away from strict academic preservation, opting instead for comprehensive physical and mental health support, bullying prevention, and robust social-emotional development. Schools are now tasked with providing comprehensive frameworks that address anxiety, promote resilience, and foster a genuine sense of belonging among diverse student populations.

This trend is highly visible in Southeast Asia. For instance, despite Thailand experiencing a 1.1 percent drop in its nationwide student population due to record-low birth rates, enrolment in the country’s international schools surged by 8.3 percent in a single year. The Thai international education sector is projected to reach a market value of 95 billion baht by 2025. This growth is largely driven by parental demand for globalised, skill-based curricula over traditional memorisation frameworks. Affluent local families are progressively choosing domestic international options over overseas boarding schools. They cite the need for holistic safety and the development of emotional intelligence as primary drivers for this decision.

To achieve this, institutions must actively balance rigorous academics with extensive pastoral care and extracurricular enrichment. A prime, real-world example of this balanced approach is Bangkok Patana, which successfully merges robust British and IB curricula with a deep commitment to well-rounded student development. By creating an environment where interculturalism and personal relationships thrive, schools like this help students internalise what it means to be responsible members of a global community.

Fostering Global Citizens in Practice

Transitioning from a strictly academic focus to a global citizenship model is not a simple process. Academic researchers have noted a critical shift in global education from traditional educare, which focuses on standard knowledge transmission, to educere, which prioritises student empowerment and critical thinking. This pedagogical transition closely matches the holistic ethos of modern schooling.

Recent scholarly investigations highlight exactly how students absorb these values. According to 2024 research from the University of Tasmania, students in the International Baccalaureate programme develop genuine global citizenship primarily through intercultural interactions and school culture, rather than just textbook learning. The study emphasises the absolute necessity for schools to cultivate a strong community culture alongside their academic programmes.

Core Pillars of Modern International Curricula

Global educational organisations, including the Council of International Schools and UNESCO, have established frameworks that anchor institutional accreditation on intercultural learning, equity, and environmental sustainability. When schools implement these frameworks, they typically rely on several core pillars to drive student success:

  • Experiential Learning: Utilising project-based learning to bridge the gap between abstract global issues and local community action. This reinforces real-world empathy.
  • Community Engagement: Incorporating core requirements, such as the Creativity, Activity, and Service components of the IB Diploma, to facilitate transformative learning and learner agency through hands-on involvement.
  • Integrated Pastoral Care: Moving away from treating wellbeing as a secondary add-on and instead weaving mental health and emotional support directly into daily academic life.
  • Intercultural Understanding: Prioritising conflict resolution and human rights education to ensure students can navigate and respect diverse cultural perspectives.

Furthermore, systemic approaches to wellbeing are gaining robust academic backing. In 2024, the Wellbeing Research Centre at the University of Oxford partnered with the International Baccalaureate to publish foundational research. This work guides schools on how to implement evidence-based approaches to both student and teacher wellbeing, proving that emotional health is inextricably linked to academic achievement. When teachers are supported and equipped with the right tools, they can create classroom environments that actively promote psychological safety and collaborative learning.

Ultimately, cultivating global citizenship is about more than preparing students for university. It is about equipping them with the resilience, empathy, and critical thinking skills required to navigate an increasingly complex world. By embracing holistic educational models, modern international schools are ensuring that the next generation is not only academically proficient but also genuinely prepared to lead and collaborate across global borders.

Daily writing prompt
If you had to give one life-changing tip, what would it be?

Responsive Exterior Lighting in Residential Design: Motion Sensor vs Dusk-to-Dawn Wall Lights

Exterior lighting is both an architectural element and a practical system. It shapes how a building is perceived after sunset, clarifies entrances and circulation routes, and affects the comfort of residents and visitors. Increasingly, wall-mounted fixtures also respond to changing conditions rather than operating at one brightness for a fixed number of hours.

Motion-sensing and dusk-to-dawn wall lights represent two different approaches to responsive illumination. One reacts to activity within a detection area; the other follows the natural cycle of daylight. Understanding their distinct behaviours helps designers and homeowners choose controls that suit the architecture, location, and pattern of use.

Lighting Controls Should Follow Spatial Use

A successful exterior scheme begins with observation. The front door, garage, side passage, patio, service area, and garden gate are used differently, so a single control strategy may not suit every wall. A frequently used entrance benefits from reliable baseline illumination, whereas a quiet side route may only need stronger light when movement occurs.

How Motion-Sensing Wall Lights Function in a Design

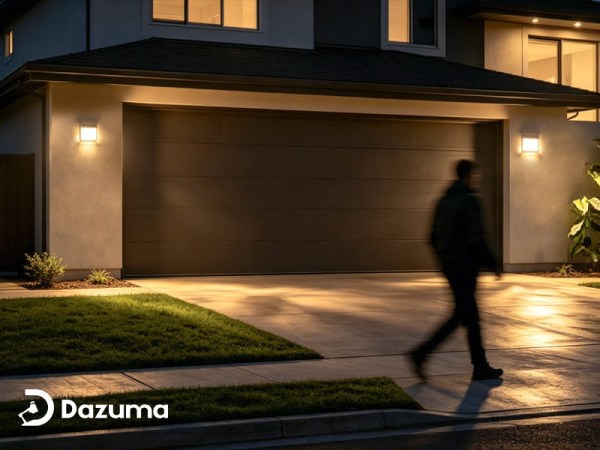
Motion-responsive fixtures activate or increase output when their sensors detect movement. This behaviour makes them useful at secondary entrances, garages, side yards, utility zones, and other locations where continuous full brightness may be unnecessary.

Properly positioned Motion Sensor Wall Lights can provide immediate visibility as someone approaches a door or moves through a passage. Their value depends on sensor placement as much as fixture style. A unit aimed toward a public pavement, road, moving branches, or neighbouring activity may trigger more often than intended.

How Dusk-to-Dawn Lighting Supports Continuity

Dusk-to-dawn fixtures use a light-sensitive control to switch on as daylight fades and turn off when sufficient natural light returns. Their predictable operation is useful where a property needs a visible entrance, house number, boundary, or circulation point throughout the night.

Dusk to Dawn Outdoor Wall Lights can establish a consistent layer of low-level illumination around a façade. They are especially suitable for primary entrances and architectural locations that should remain legible even when no person is currently present.

Comparing Presence-Based and Daylight-Based Control

The central distinction is what causes the response. Motion sensors react to people, vehicles, or other movement. Dusk-to-dawn controls react to ambient light levels. This difference affects the visual character of the property.

A motion-only scheme can leave a wall dark until activity occurs, creating a noticeable transition from darkness to brightness. A dusk-to-dawn scheme maintains continuity but may provide light for longer periods. The choice should reflect whether the design prioritises event-based visibility or an uninterrupted nighttime identity.

A Combined Strategy Can Offer Better Balance

The two approaches do not have to be mutually exclusive. A primary entrance may maintain a soft dusk-to-dawn glow, while a secondary passage uses motion activation. Some control systems can also provide low output after dark and increase brightness temporarily when movement is detected.

This layered strategy supports orientation without keeping every fixture at full output. It also creates hierarchy: the front entrance remains visually prominent, while less-used areas respond only when needed.

Fixture Form Still Matters

Smart control does not compensate for poor proportions or uncomfortable glare. Wall lights remain part of the façade during the day, so their scale, material, finish, and relationship to doors and windows require architectural consideration.

Shielded or diffused fixtures can reduce direct glare. Downward light may suit a narrow passage, while an upward-and-downward pattern can emphasise stone, brick, or textured plaster. At an entrance, the fixture should provide useful facial visibility without exposing occupants to a harsh bare source.

Coordinate Colour and Brightness Across the Exterior

Responsive fixtures should still belong to one lighting composition. Large differences in colour temperature can make adjoining walls appear disconnected. Warm white light often complements residential materials, while a consistent neutral tone may suit a sharper contemporary façade.

Installation and Evaluation

Before permanent installation, evaluate each fixture’s likely field of view, nearby obstructions, daylight exposure, and relationship to other lights. After installation, test the system by approaching from every intended route and observing it from interior rooms as well as outdoors.

Fixtures must be suitable for their level of exposure to moisture and weather. New wiring, control integration, or uncertain electrical work should be completed by a qualified professional.

Conclusion

Motion-sensing lights are most effective where illumination should follow activity. Dusk-to-dawn lights are better where architectural visibility and orientation should continue throughout the night. In many residential projects, combining the two produces a more responsive and balanced result.
The control method should be treated as part of the design, not merely a technical accessory. When sensors, fixture form, brightness, and spatial use are planned together, exterior wall lighting can improve function while preserving the character of the architecture after dark.

Daily writing prompt
If you had to give one life-changing tip, what would it be?

How to Extend Portable Power Station Runtime?

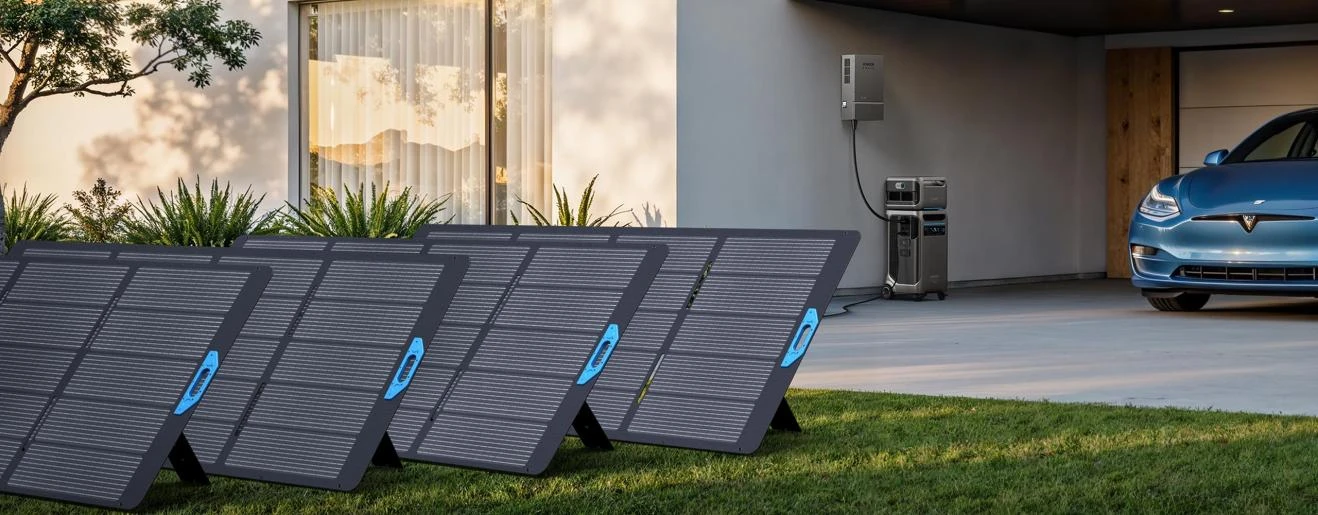
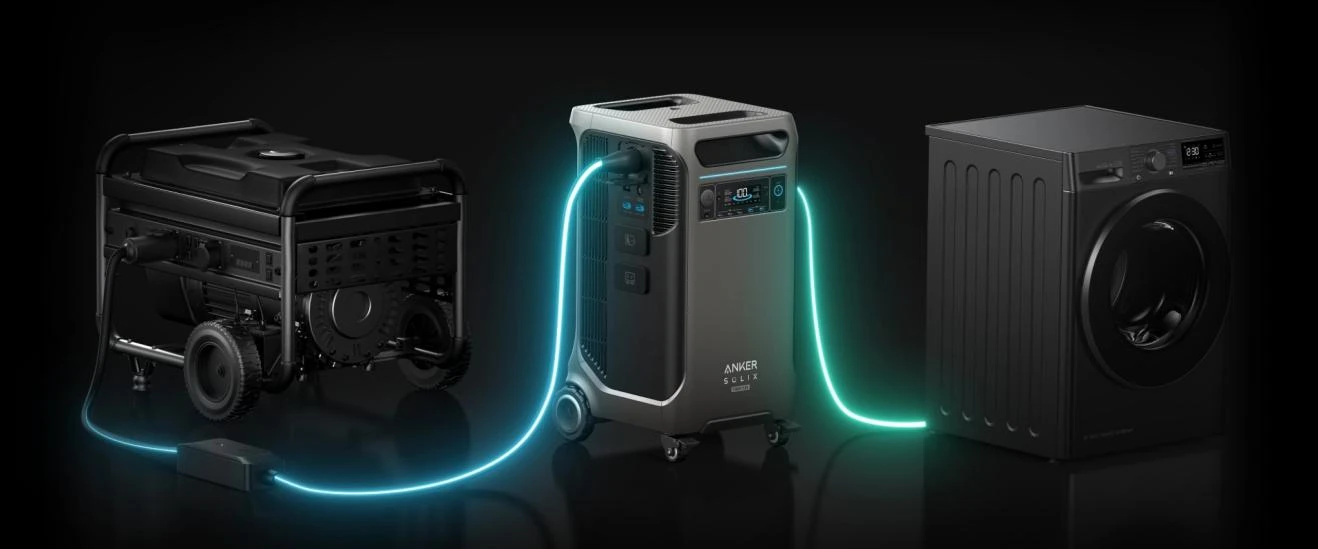
Extending portable power station runtime starts with using less energy, matching loads to battery capacity, and preparing reliable ways to recharge. Many users focus only on battery size, but actual backup time depends just as much on what you power, how you charge, and how efficiently the station operates between sessions. Small adjustments, such as turning off idle AC output, avoiding unnecessary devices, and planning solar or wall charging in advance, can add meaningful hours of use. With the right habits, you can get longer backup time without changing your core equipment at all.

6a6c0b955b9ae.webp

Reduce Energy Consumption to Maximize Runtime

Prioritize Essential Devices and Avoid Unnecessary Loads

The fastest way to extend runtime is to decide which devices truly matter. Start with essentials such as phones, lights, routers, medical equipment, or a small refrigerator, then disconnect comfort items that add steady drain without much value. High-wattage appliances, space heaters, and large cooking devices can empty a battery far faster than expected. It also helps to avoid plugging in chargers or electronics that remain in standby mode, because small phantom loads add up over several hours. Create a simple priority list before an outage or trip so you know what stays on first. That approach prevents waste and preserves power for the devices you actually need most.

Use Energy-Efficient Charging Methods and Settings

Charging devices efficiently can preserve more stored energy for longer use. Whenever possible, charge phones, tablets, cameras, and similar electronics through DC or USB outputs instead of running the inverter for small loads, since AC conversion introduces losses. Lower screen brightness, enable battery saver modes, and charge devices before they drop to critically low levels, because deep recharging multiple items at once increases demand. If your power station offers app-based monitoring, use it to spot inefficient usage patterns and adjust output settings in real time. The Anker app for the Anker SOLIX F3800 Plus Portable Power Station helps track charging, usage, and battery status, making it easier to reduce waste.

Optimize Portable Power Station Usage for Longer Backup Time

Understand Battery Capacity and Device Power Demands

Longer backup time begins with knowing how much energy your station stores and how quickly your devices consume it. Battery capacity is usually measured in watt-hours, while device demand is measured in watts. Divide usable watt-hours by the total running wattage to estimate runtime, then reduce that figure slightly to account for conversion losses. A 100-watt load will run far longer than a 1,000-watt appliance, even on the same unit. Check both running wattage and startup surges, especially for refrigerators, pumps, and tools. When you understand these numbers, you can rotate loads, avoid overloads, and make smarter decisions about what to power continuously versus only when needed.

Manage AC Output, Charging Cycles, and Standby Consumption

Portable power stations often lose energy through unnecessary inverter use, repeated partial charging habits, and standby draw from connected equipment. Turn on AC output only when you need to power AC devices, then switch it off afterward to reduce idle consumption. Unplug adapters, chargers, and appliances that continue drawing power even when they seem inactive. Try to group charging sessions instead of cycling the battery for many small, scattered tasks throughout the day. Fewer unnecessary cycles can support better long-term battery performance. It also helps to monitor output patterns regularly so you can catch waste early. Small operational changes like these often deliver noticeable runtime gains without changing battery size or usage goals.

6a6c0ba2642e7.webp

Improve Runtime Through Better Preparation and Maintenance

Plan Recharging Options Before Extended Use

Preparation matters as much as conservation when you need longer runtime. Before camping, road travel, or outage season, map out how and when you can recharge. Wall charging is often the fastest reset between uses, while solar can sustain longer off-grid operation if conditions are good. The Anker SOLIX F3800 Plus Portable Power Station supports up to 3,200W solar input with dual MPPT across an 11-165V range, allowing a full recharge in under 2 hours in optimal sunlight. It is also compatible with 240V AC wall outlets for faster recharging and 240V pure sine gas generators for extended outages, with 6,000W bypass support. Redundant charging options greatly improve uptime.

Store and Maintain the Power Station Properly

Good maintenance helps your power station deliver reliable runtime over the long term. Store it in a cool, dry place away from direct heat, freezing conditions, and excessive humidity, because temperature stress can reduce battery performance. If you will not use it for a while, keep the battery at a moderate state of charge rather than fully empty or permanently topped off. Check the unit periodically, recharge it as recommended, and inspect cables, ports, and ventilation openings for dust or damage. Keep firmware updated when applicable so charging behavior and system monitoring remain accurate. Consistent care protects battery health, supports stable output, and helps preserve expected backup time when you need it.

Conclusion

To extend portable power station runtime, focus on three things: reduce unnecessary consumption, use the station more efficiently, and prepare dependable recharging options. Prioritizing essential devices, limiting AC inverter use, and understanding watt-hour versus watt demand can quickly stretch available power. Better habits, such as avoiding standby losses and maintaining proper storage conditions, also support stronger long-term performance. When you pair smart daily operation with advance planning for wall, solar, or generator charging, your power station becomes far more dependable. Runtime is not only about battery size. It is the result of informed power management before, during, and after each use.

Daily writing prompt
Who is the fictional character you relate to the most?